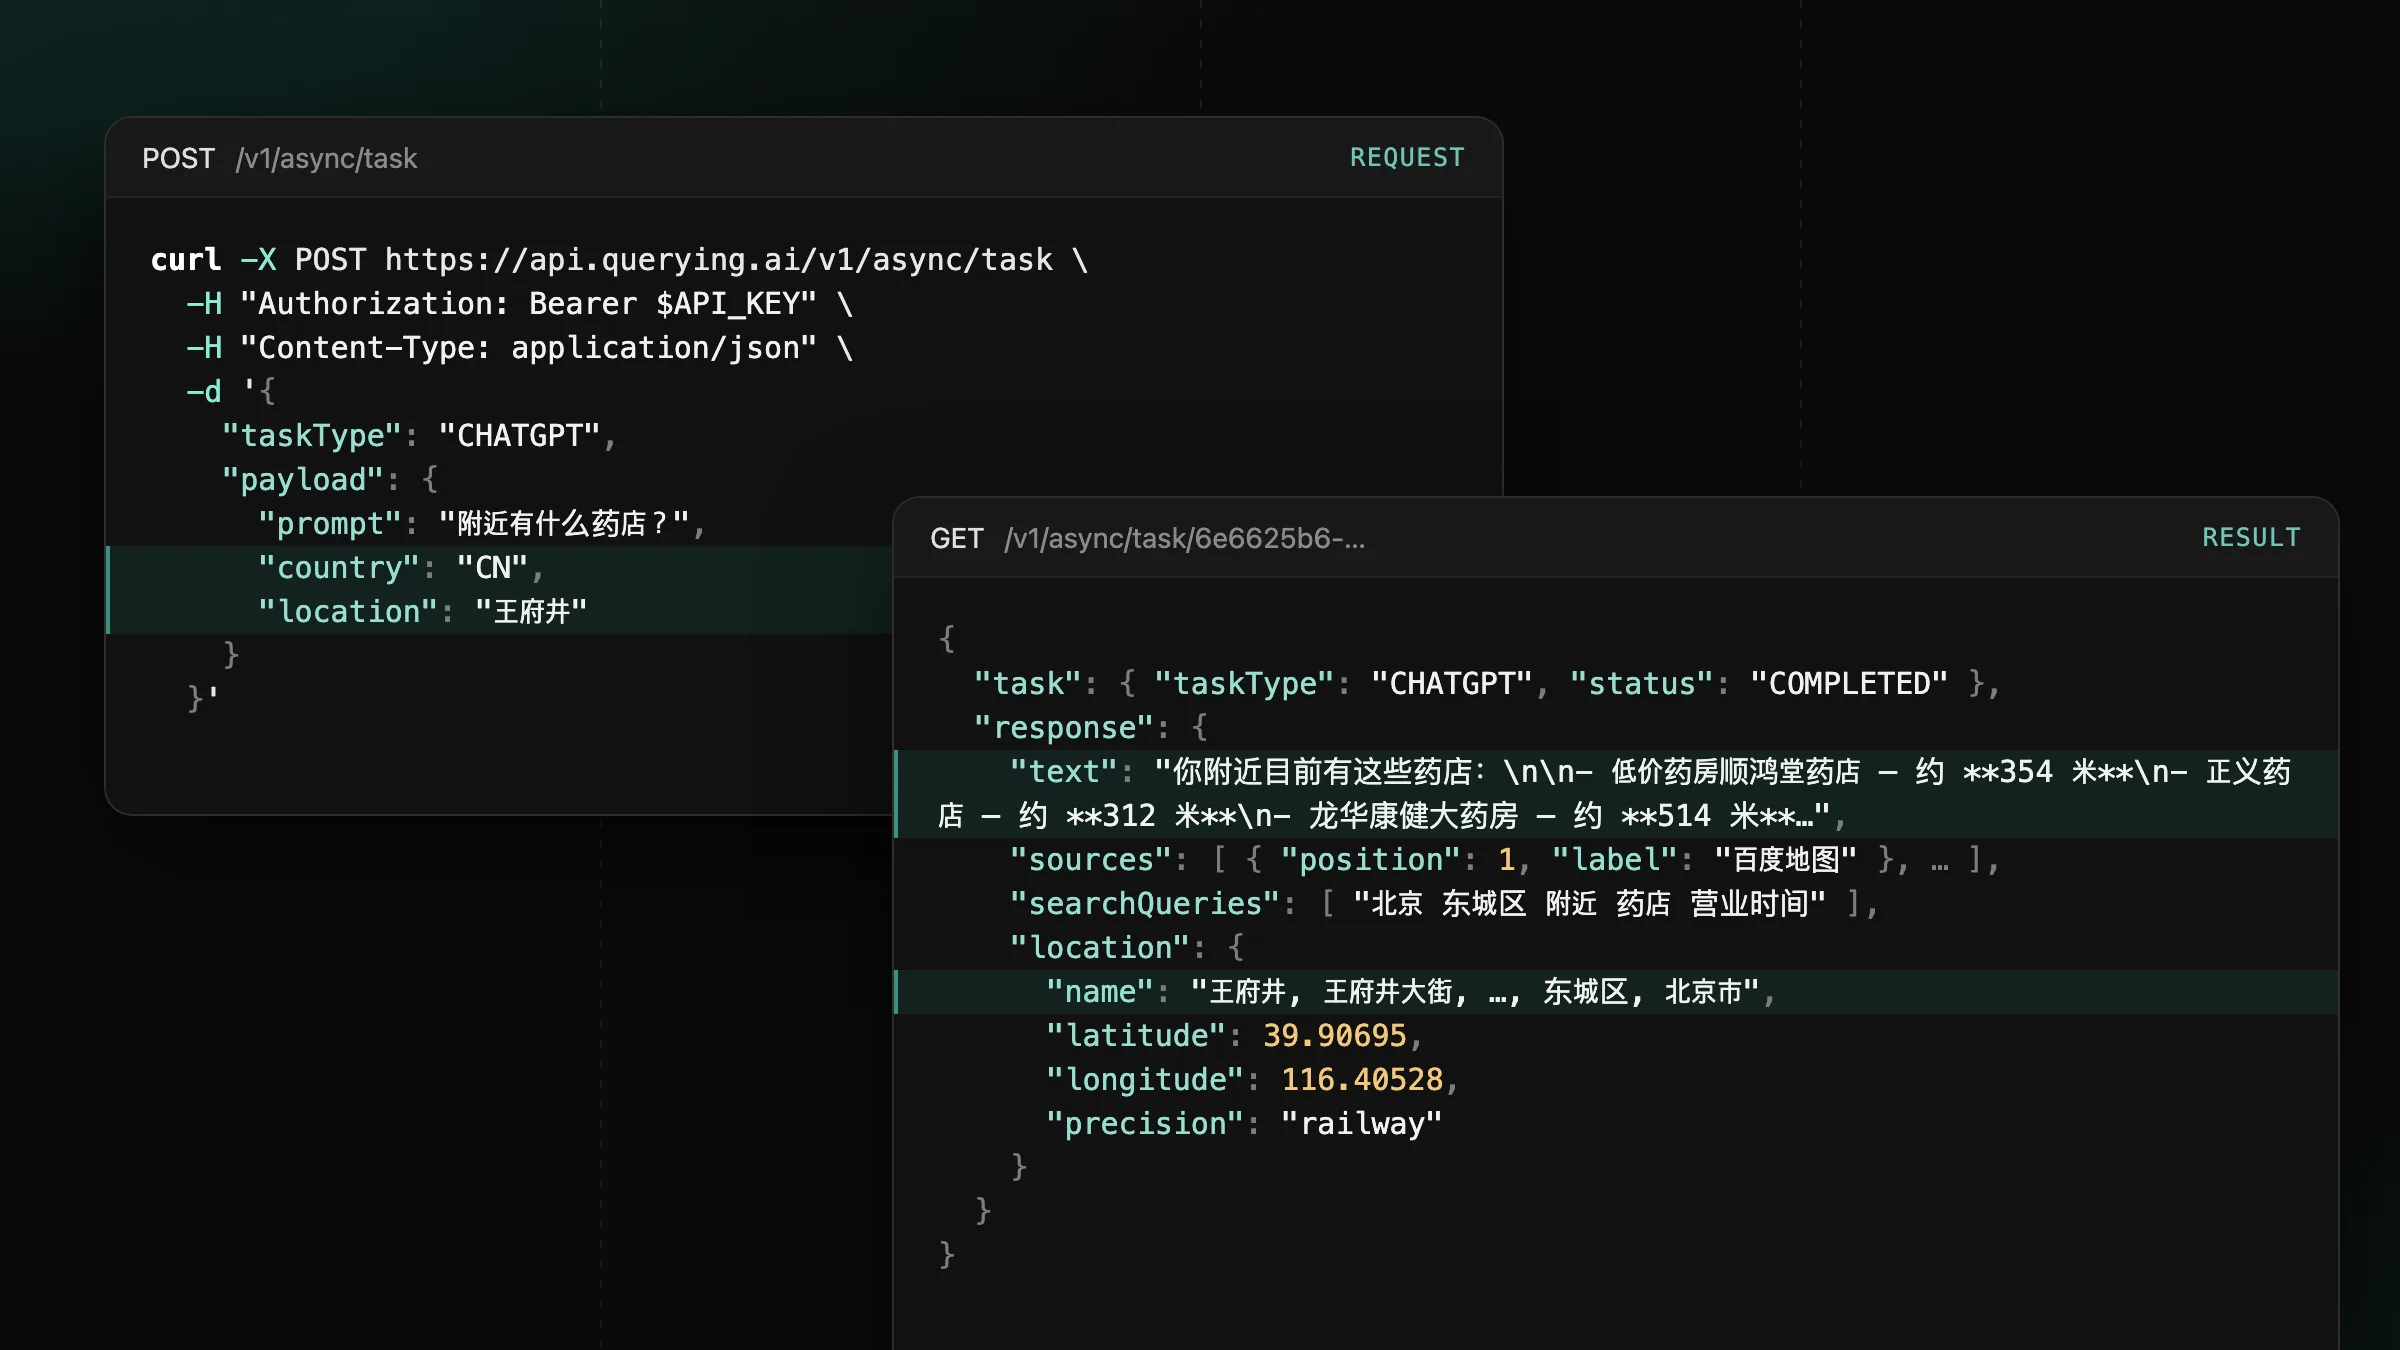
Now supporting mainland China on ChatGPT, Gemini and Google
Set country to CN or HK on CHATGPT, GEMINI and GOOGLE tasks to get the answers users in mainland China and Hong Kong see.
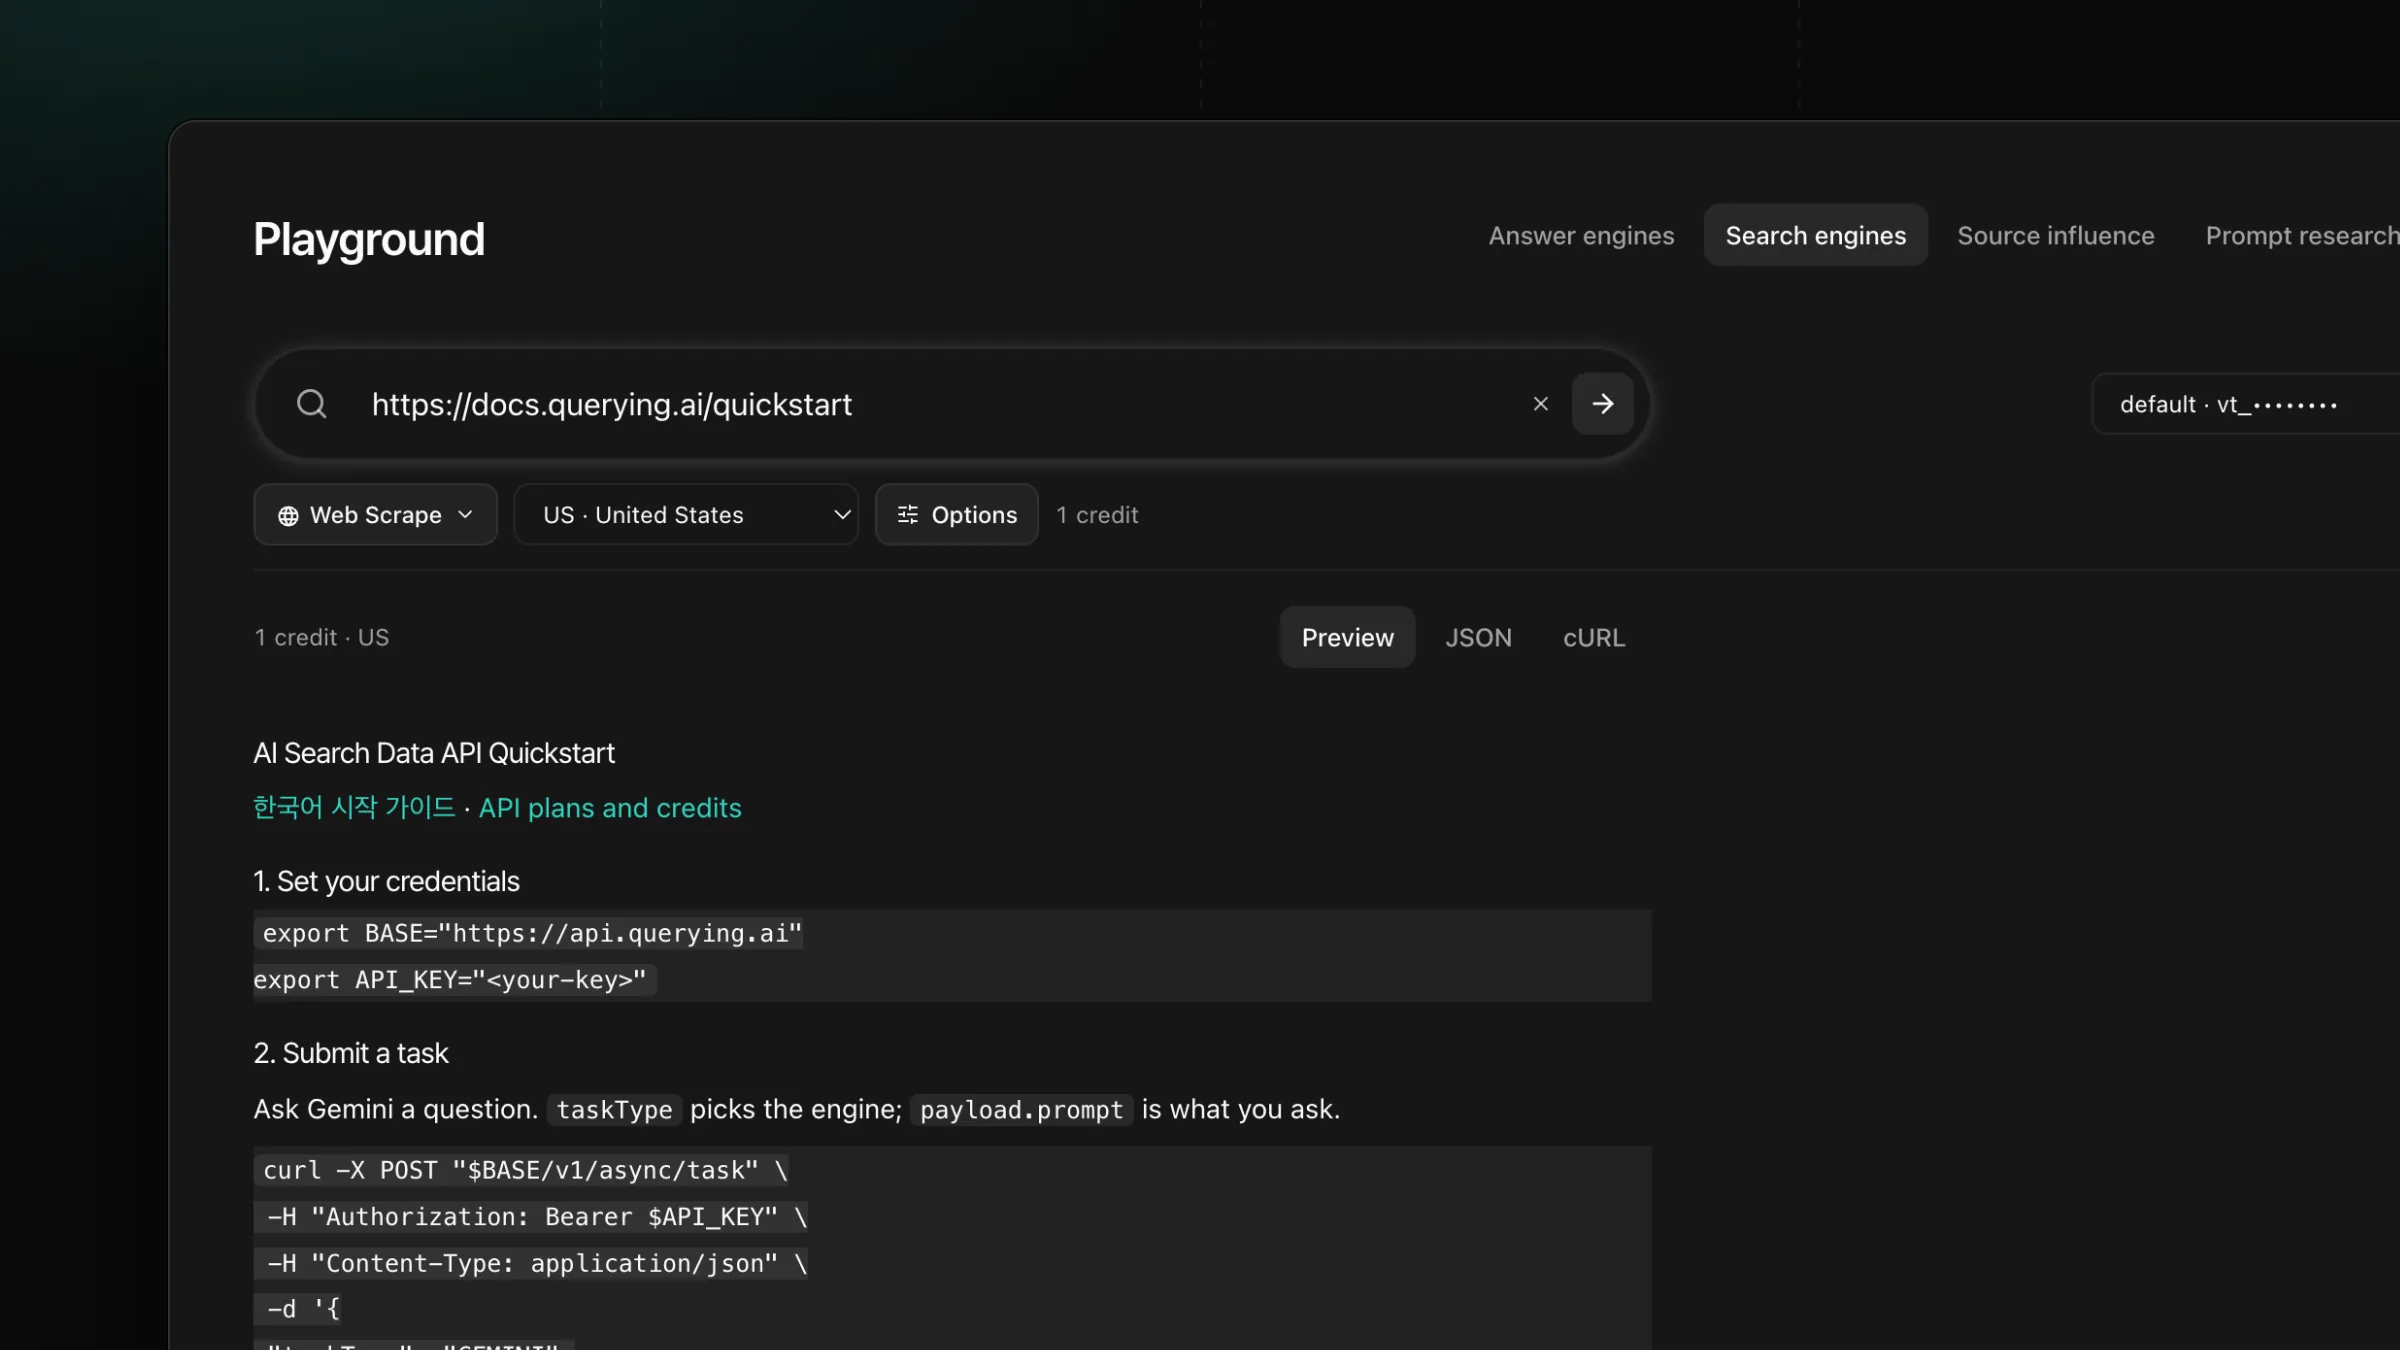
Web Scrape extracts the main content of a URL as Markdown for 1 credit per completed request.
markdown: the page’s main content with its headings, paragraphs, lists, tables, links and images, with the site’s header, footer and navigation removed.title, description, author, publishedAt, siteName, language and image whenever the page declares them.finalUrl and statusCode: the address after redirects and the status the site answered with.images: every picture in markdown, in the order it appears, with its alt text.Send a public http or https URL of up to 2,048 characters. Web Scrape opens the page, renders pages that a script draws, such as shop product pages, and keeps the content a reader comes for: the text, the tables and the pictures. The result is clean Markdown, ready to store, search or analyze.
maxChars sets the length, from 1,000 to 200,000 characters (100,000 by default). A long page stops at a paragraph break and sets truncated: true. country (US by default) sets the language and region the page is requested for. A PDF, a page that answers 404 or 410, or a site that refuses the request ends the task with PAGE_UNAVAILABLE and the site’s answer in the message.
link from GOOGLE_SERP results to read the pages that rank for a query.scrape_page.Send the request with your API key in the Authorization header.
curl -X POST https://api.querying.ai/v1/async/task \
  -H "Authorization: Bearer $QUERYING_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "taskType": "WEB_SCRAPE",
    "payload": {
      "url": "https://docs.querying.ai/quickstart",
      "country": "US"
    }
}'taskTypestringRequiredCHATGPT or GOOGLE.payload.urlstringRequiredpayload.maxCharsintegermarkdown, 1,000 to 200,000. Default 100,000. A longer page ends at a paragraph break and carries truncated.payload.countrystringUS.webhook.urlstringidempotencyKeystringA finished task looks like this, trimmed for length.
{
  "success": true,
  "task": {
    "id": "910017b1-4fd5-4bc7-8895-bbe6b1b0d1df",
    "taskType": "WEB_SCRAPE",
    "status": "COMPLETED",
    "createdAt": "2026-10-02T15:48:34.088Z"
  },
  "credits": { "creditsToCharge": 1, "creditsCharged": 1 },
  "response": {
    "url": "https://docs.querying.ai/quickstart",
    "finalUrl": "https://docs.querying.ai/quickstart",
    "statusCode": 200,
    "title": "AI Search Data API Quickstart",
    "description": "Submit a task, receive a result — with webhooks or by polling.",
    "siteName": "querying.ai",
    "language": "en",
    "markdown": "# AI Search Data API Quickstart\n\n[한국어 시작 가이드](https://querying.ai/ko/guides/quickstart) · [API plans and credits](https://querying.ai/en/pricing)\n\n## 1\\. Set your credentials\n\n```shellscript\nexport BASE=\"https://api.querying.ai\"\nexport API_KEY=\"<your-key>\"\n```\n\n…",
    "images": [],
    "truncated": false
  }
}task.statusstringQUEUED, PROCESSING, then COMPLETED with the answer or FAILED with error.credits.creditsChargedintegerresponse.markdownstringresponse.titlestringdescription, author, siteName and language when the page declares them.response.publishedAtstringresponse.finalUrlstringstatusCode.response.imagesarraymarkdown, in reading order, each with url and alt.response.truncatedbooleantrue when markdown reached maxChars and ends at a paragraph break.The request returns the task right away with status QUEUED. Poll GET /v1/async/task/{id} until status is COMPLETED or FAILED, or add webhook.url and the finished task arrives at your server with the same task, credits and response. Results stay available for 24 hours after a task finishes.
curl https://api.querying.ai/v1/async/task/$TASK_ID \
-H "Authorization: Bearer $QUERYING_API_KEY"Each completed page uses 1 credit.
Set country to CN or HK on CHATGPT, GEMINI and GOOGLE tasks to get the answers users in mainland China and Hong Kong see.
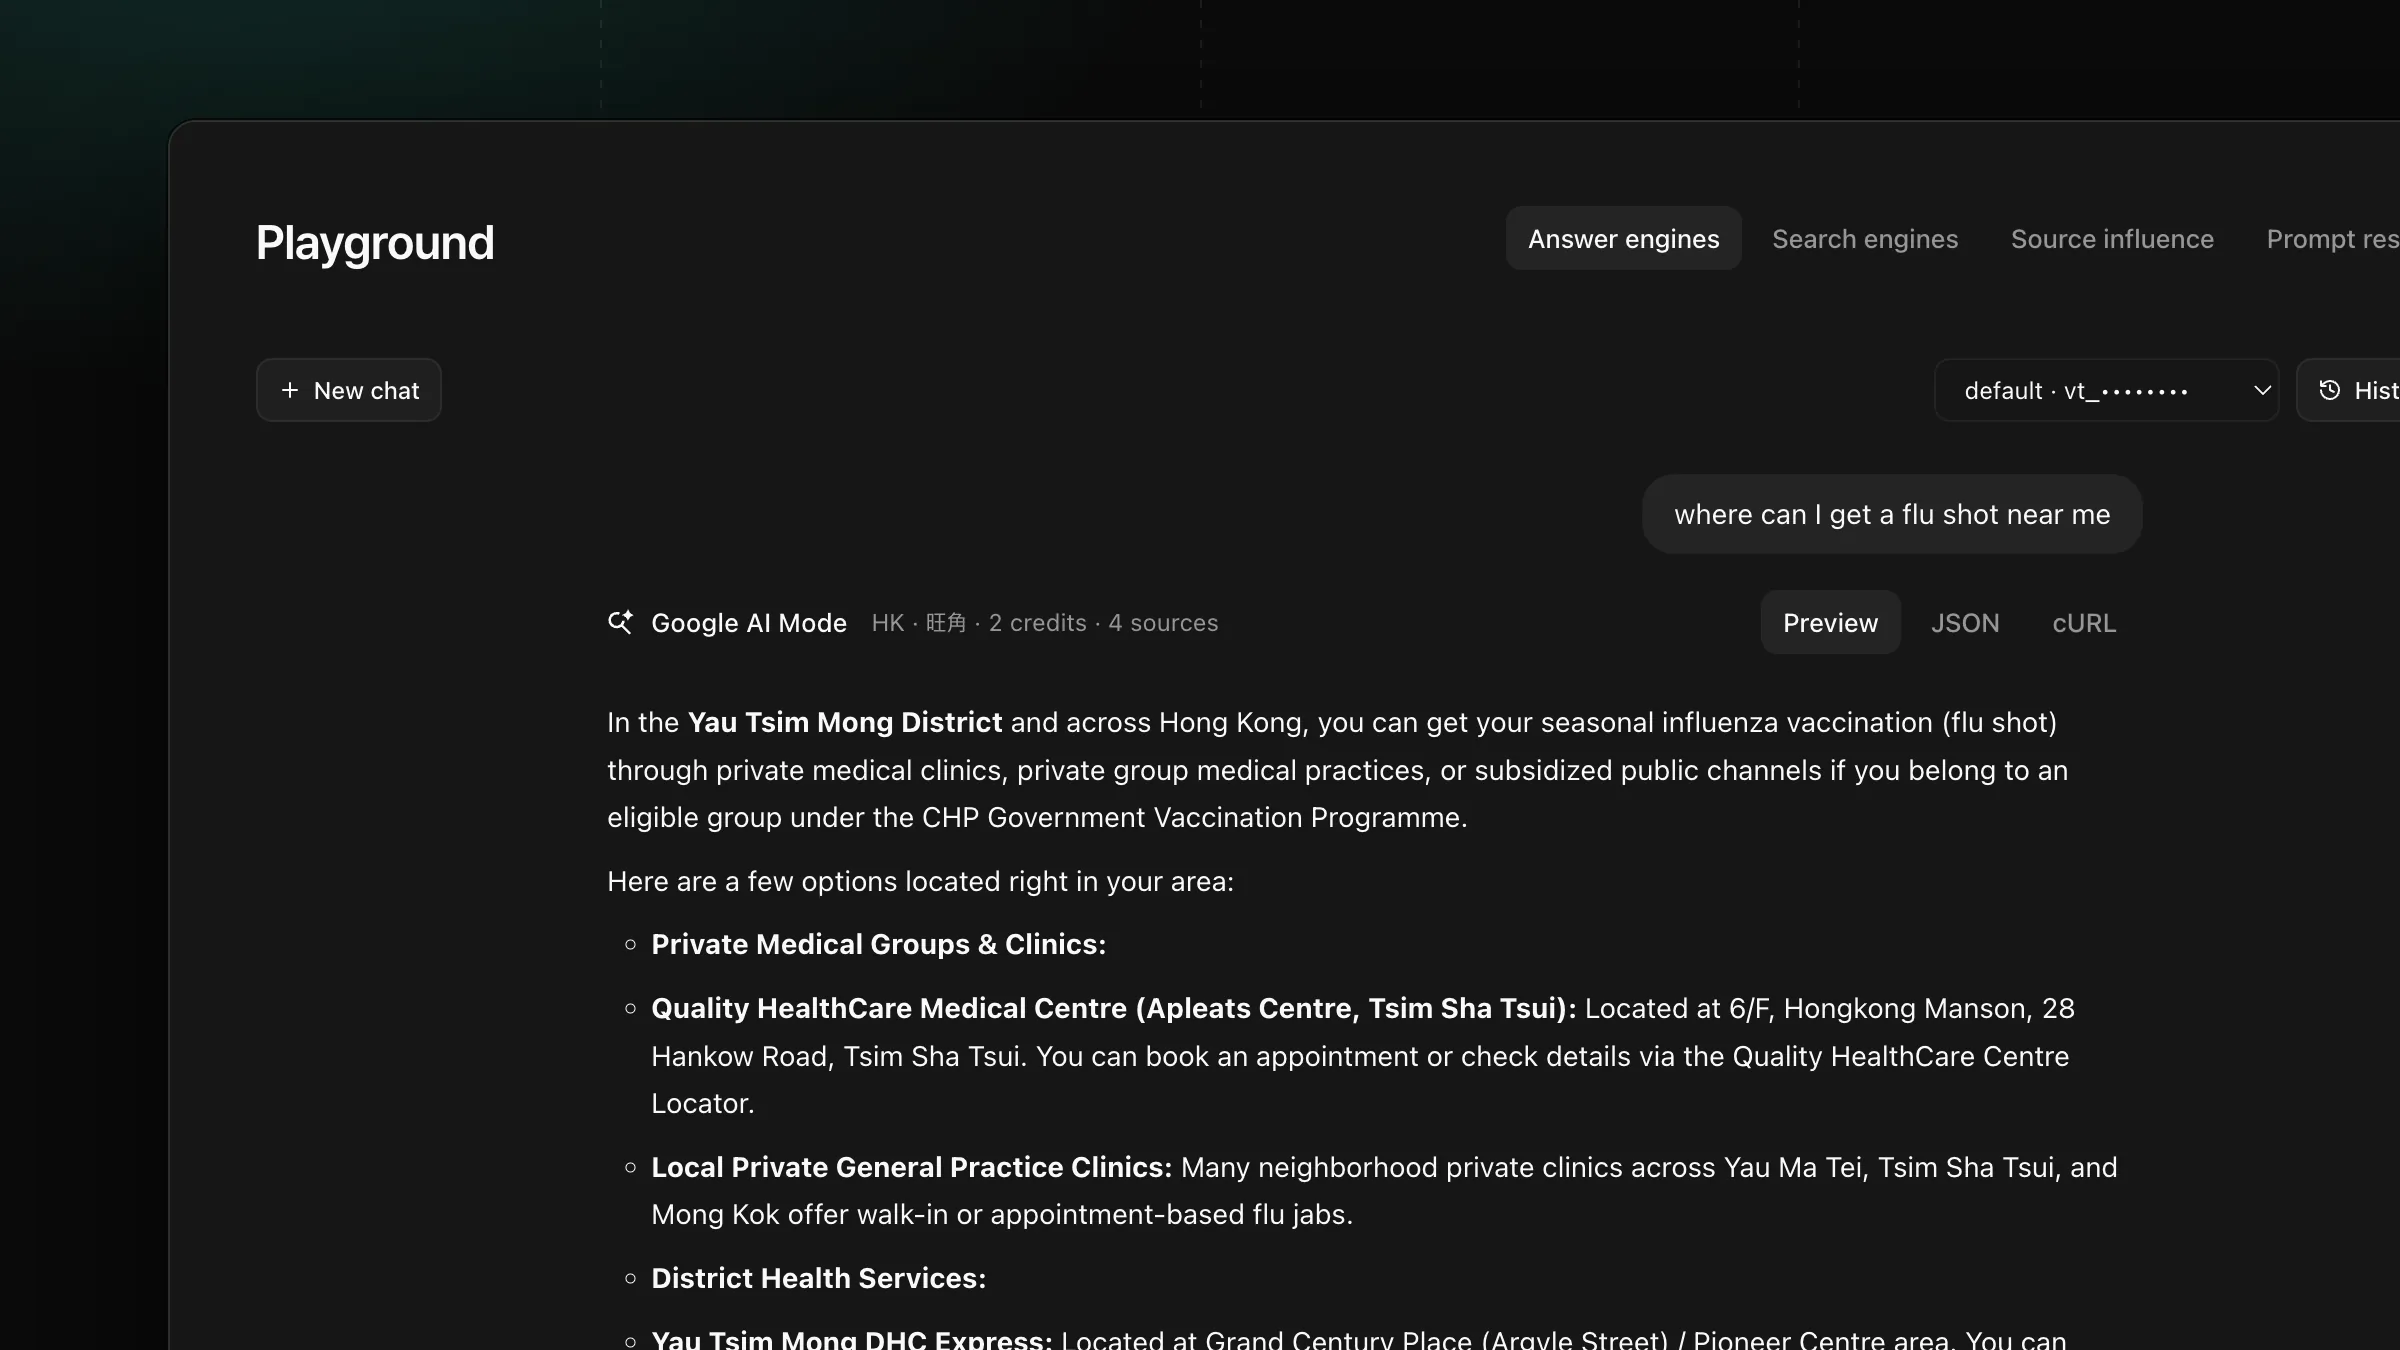
Set payload.location on GOOGLE, AIMODE and GOOGLE_SERP tasks to get the AI Overview, AI Mode answer and search results a user at that place sees.
Get new product updates in your inbox.